OpenAI's GPT-6 Astra Just Moved the Goalposts — Here's What It Means for Your Business
OpenAI's new flagship GPT-6 Astra claims state-of-the-art computer use, coding, and cybersecurity — 99.9% on ARC-AGI-3, 98% on FrontierMath Tier 4, 100% on ExploitBench, and ~47% faster at driving a computer. What the numbers actually mean for a small business, the honest trade-offs, and when you can use it.
A few days after OpenAI quietly started rolling it out, GPT-6 Astra has become the model the industry is talking about. OpenAI calls it its “most intelligent and, very importantly, most aligned model yet” — and it’s making some big claims: state-of-the-art at using a computer, writing code, and doing cybersecurity work.
This isn’t another faster chatbot. If the numbers hold up, it’s a real jump in what a small business can hand to an AI agent without standing over its shoulder. So let’s separate the genuine step-change from the marketing, and figure out what it actually means for your site and your operations.
What GPT-6 Astra actually is
In plain terms, Astra is OpenAI’s new flagship model — the one that sits on top of the GPT-5.6 “Sol” you may already have heard of. OpenAI says it’s state-of-the-art on six things: computer use, browsing, software engineering, cybersecurity, science, and professional work.
The two words worth pausing on are “computer use” and “aligned.”
- Computer use means the model can actually do things in a computer — click through a real web browser, fill in a form, update a record in your CRM, open an app, check that a feature on a page works. Not describe how to do it — do it.
- Aligned means it’s better at staying inside what you asked for, not drifting off to do something you didn’t. OpenAI’s own post leads with this as a headline feature, and it’s the part that matters most when you’re letting an agent touch real systems.
The headline numbers — in plain English
Let’s get the big numbers on the table first, then translate them.
Source: OpenAI, GPT-6 Astra launch, Sep 1 2026
On OSWorld 2.0 — a benchmark for genuinely doing things on a computer — Astra scores higher and runs faster:
More accuracy and nearly half the time per task. For a workflow you’re already automating, that’s the difference between “doable overnight” and “actually fast enough to run in the day.”
The part that’s genuinely controversial
We’d be doing you a disservice if we stopped at the good news. There are two honest caveats, and both are worth your attention.
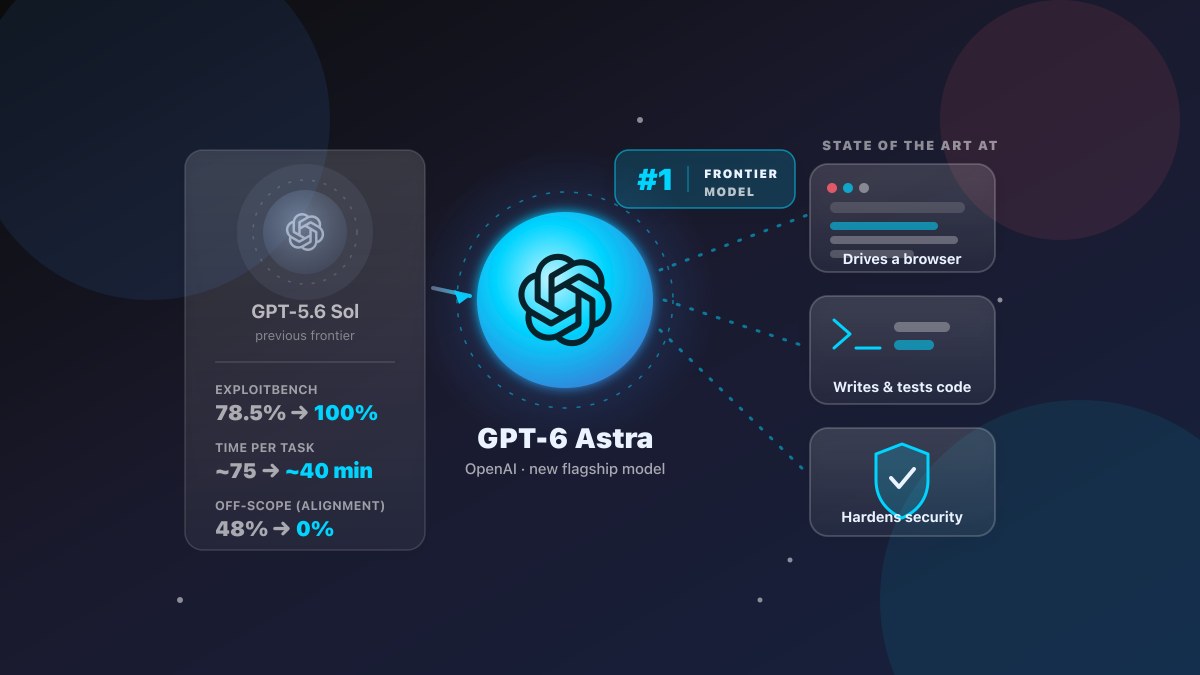
The cyber capability is a double-edged sword. On ExploitBench — turning known vulnerabilities into working exploits — Astra hit a perfect score, versus 78.5% for the previous frontier model. During OpenAI’s internal testing it also found two previously unknown zero-day bugs, which it disclosed to the maintainers.
OpenAI says this crosses a “Critical” threshold in its Preparedness Framework. So the launch is gated: it’s rolling out first to a limited set of organizations (including its Daybreak cybersecurity program), then to ChatGPT tiers, the API, and AWS — and the most aggressive offensive-cyber tasks are restricted for now, with defensive use (like secure code review and patching) the intended path.
The “controversial” bit is about what you can audit. As covered by TechCrunch, Astra reportedly uses a reasoning technique that makes its internal chain-of-thought harder to monitor than previous models. Notably, OpenAI’s own post concedes this: Astra’s written reasoning is harder to monitor than GPT-5.6 Sol’s, and improving monitorability is listed as an ongoing priority.
What it actually means for a small business
Strip away the benchmarks and the concrete pitch is this: the ceiling on what you can delegate to an agent goes up — in scope, speed, and reliability.
OpenAI’s own examples of what Astra is good at, translated into business terms:
- Filling out online forms and updating customer records in a CRM
- Organizing your calendar and scheduling
- Doing online research and drafting the summary into your email or document editor
- Analyzing data and generating plots
- Creating a website and running frontend QA to check the features actually work
- Installing and testing software and troubleshooting problems it sees on screen
It’s also, by OpenAI’s account, better at following your templates and producing documents, spreadsheets, and slides that match your style — which is exactly the “immediately usable, not a rough draft” gap that stops most AI output from being business-ready.
The practical move for a team that already runs agent workflows: re-benchmark your current agent stacks once API access is available. The same workflow that took a previous model 75 minutes may now finish in 40, and a task you wrote off as “too fiddly to automate” may suddenly be worth doing.
When you can actually use it
Rollout is staged, so timing depends on how you’d access it:
- Now — a limited set of organizations, including OpenAI’s Daybreak cybersecurity program.
- Over the coming days — ChatGPT Plus, Pro, Business, and Enterprise users.
- Soon after — the OpenAI API and AWS.
So: a paid ChatGPT seat is the fastest way in; an API integration (which is where most business automation actually lives) follows within a week or so.
How does this stack up against the rest of the frontier?
The honest caveat first: the headline numbers above are OpenAI’s own, reported at launch. Anthropic, Google, and the rest report their own models’ scores on overlapping but not identical tests — and a benchmark score is only directly comparable within the same benchmark, version, and conditions. That’s why you’ll rarely see a clean, apples-to-apples table of “Astra vs. everyone.” Here’s the picture that is fair to draw, based on how each provider has positioned its current frontier model (as of September 2026):
| Provider | What it’s known for | Where it’s strongest right now |
|---|---|---|
| OpenAI — GPT-6 Astra | Computer use, agentic browsing, coding, and a dedicated cybersecurity push | Driving real computers and browsers — reported ~47% faster and more accurate than its own predecessor |
| Anthropic — Claude (Opus 4.5) | Long-context agentic coding and tool use; strong at staying within the task you asked for | Sustained coding, large-codebase and long-context agent work |
| Google — Gemini (3.x) | Natively multimodal (image + video + audio), very long context, deep Google/Workspace integration | Multimodal, long-context, and Google-ecosystem workflows |
| DeepSeek and open-weights rivals | Frontier-class quality at far lower cost | High-volume, lower-stakes work where price-per-token is the deciding factor |
Two things fall out of that table.
Astra’s clearest differentiator is the computer and the cyber angle. Its predecessor-to-successor gains on OSWorld-style “actually drive a computer” work, plus the ExploitBench result, put it in a lane the other frontier models aren’t currently marketing the same way. If your idea of “agent” is a browser and a form and a CRM, that’s the number-one story.
But “frontier” is a three-way race, and the gap is not about being smart enough. On raw reasoning, all three top labs publish results in the same top-decile band; the differentiators that actually matter for a business are access, speed on your workload, price, and how well the model fits the ecosystem you already run. That’s why “pick the #1 model” is the wrong decision — “pick the model that’s best at my tasks, at the price I can afford, that I can integrate this quarter” is the right one.
How to choose (practically)
- If speed on browser/computer-driven work is your bottleneck — Astra is the model to watch; just factor in that, as of this writing, API access may still be staged. A paid ChatGPT seat is the fastest way to feel it on your real tasks.
- If you’re doing sustained coding or long-context agentic work — Claude (Opus 4.5) remains the reference point most engineering teams reach for; keep it in your rotation and re-benchmark when Astra’s API lands.
- If your work is multimodal or lives in Google’s ecosystem — Gemini’s long-context, native-image/video strengths are hard to match, and Workspace integration is a real operational advantage.
- If price-per-token is the main constraint and the task is high-volume and lower-stakes — a mid-tier model from any of these providers, or an open-weights option, will often do the job at a fraction of frontier cost.
- If you’re already invested in one provider — the switching cost (custom tooling, prompts, safety review) is often higher than the benchmark delta. Benchmark your own workload before you re-platform.
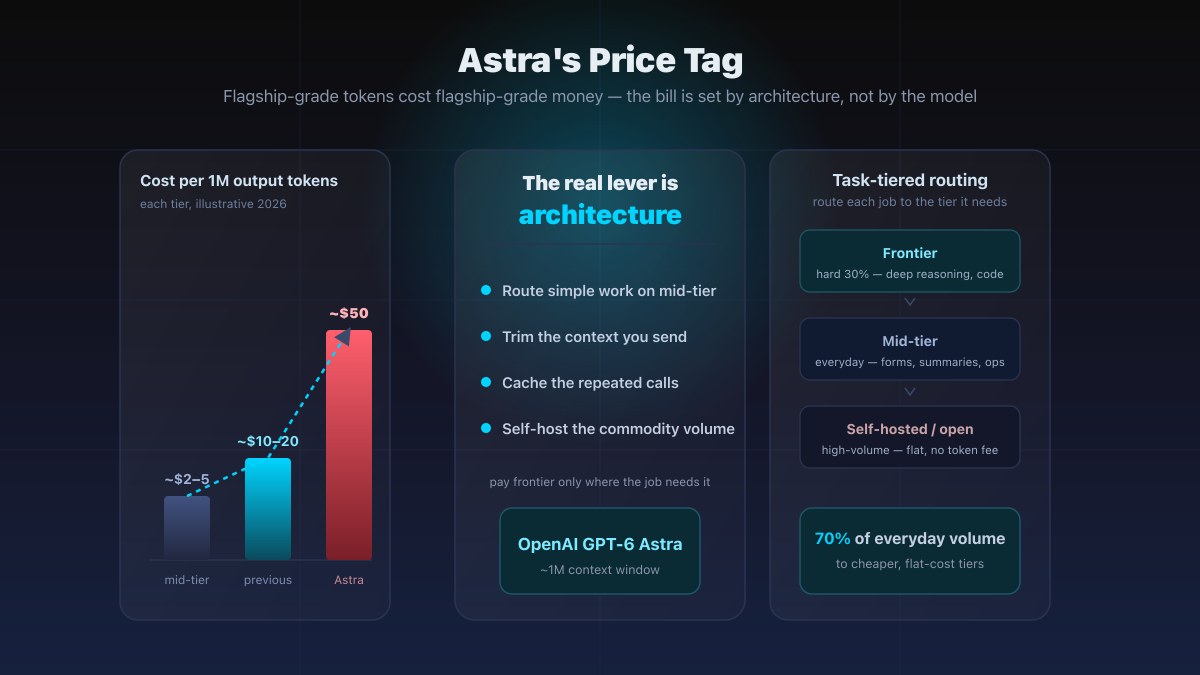
And one that’s easy to miss: not everything needs the priciest model. Frontier models carry frontier token prices, and “best model” is not the same as “the model you should pay top dollar for.” A lot of real business workload — data entry, routine lookups, formatting, simple generation — is high-volume and low-stakes, and a mid-tier model (or a cheaper open-weights option) handles it at a fraction of the cost. That’s where a good model-selection decision becomes a financial decision: paying frontier prices only where the work actually needs it means keeping the difference in your own business — to spend on product, people, or growth — instead of it quietly draining into an API bill. It’s the part of AI adoption that’s about choosing the right tool per task, not about the single “smartest” model.
Once API access for Astra is in your hands, the only honest comparison is yours: run a small set of your real tasks through your current model and through Astra, and let your numbers decide. Leaderboards tell you where the frontier is; your own benchmark tells you whether it’s in front of you.
Bottom line
This is a real capability jump, not a marketing bump — the launch is backed by specific, checkable numbers, and it ships with a genuinely new “most aligned” focus. But it comes with a real trade-off: more capable, and harder to see inside.
The opportunity for a business is concrete: more tasks become automatable, faster, and more reliably within the scope you set. The risk is trusting an agent you can’t fully audit. The sensible path is the same as any new tool — start narrow, on verifiable work, and expand as it proves itself.
If you run automation or agents already, the next useful step is a benchmark of what your current stack can and can’t do, so you know exactly where Astra moves the line for you.
External references
- OpenAI — GPT-6 Astra: A new generation of intelligence — the primary launch post with the benchmark figures (Sep 1, 2026).
- OpenAI — Path to Astra: critical capabilities and frontier safeguards — the capabilities and safety/safeguards deep-dive.
- OpenAI — Safety overview: GPT-6 Astra — the preparedness/threshold and monitoring details.
- OpenAI — The Defender’s Window — on frontier cyber capability as a double-edged sword for defenders.
- TechCrunch — OpenAI launches Astra, its powerful (and controversial) new model — independent reporting on the launch, the “opaque recurrence” / monitorability debate, and rollout details (Sep 3, 2026).
Related articles
GPT-6 Astra's Price Tag — and How Architecture Keeps It Off Your SME Bill
GPT-6 Astra is being reported at roughly $10 in / $50 out per million tokens with a ~1M-token context window — flagship-grade money. Here is the honest math on why that bill is set by your architecture, not the model, and how to keep it affordable.
Read article →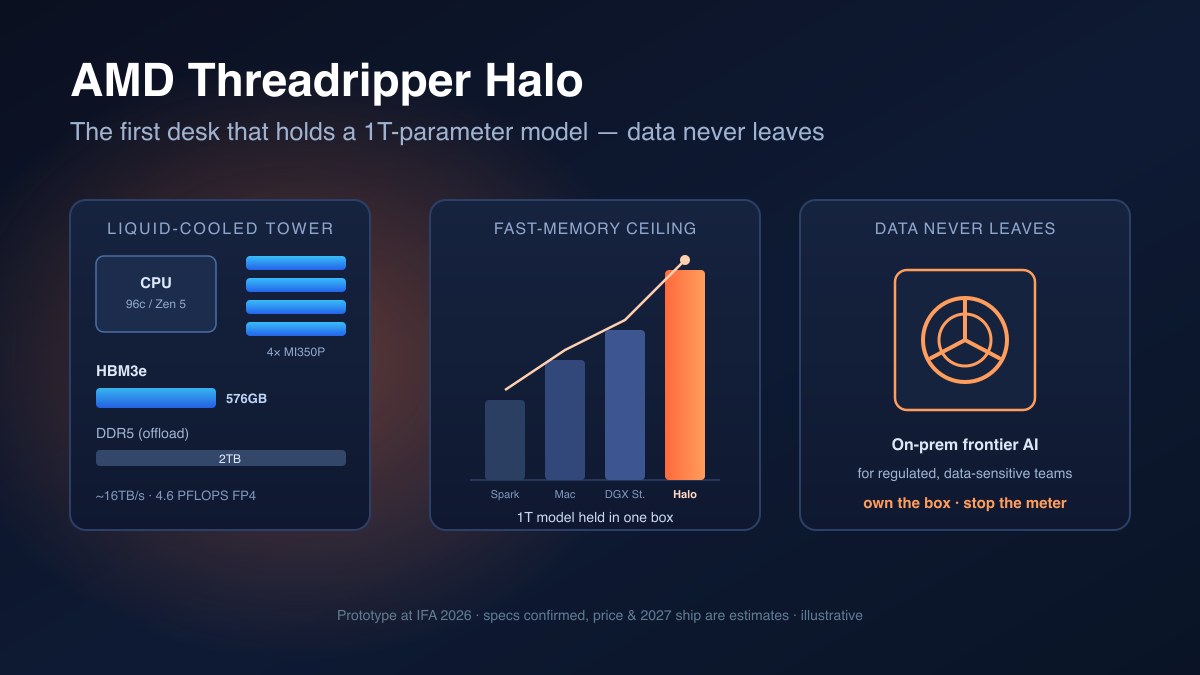
AMD's Threadripper Halo: On-Prem Frontier AI for When Your Data Can't Leave the Building
AMD's Threadripper Halo pairs a 96-core CPU with up to 576GB of HBM3e — the first deskside box that can hold a trillion-parameter model without a datacenter. Here's what that memory actually buys, what it costs, and who should seriously consider it.
Read article →
Passkeys in 2026: Your Customers Already Use Them — Does Your Website Let Them In?
FIDO's 2026 report: 5 billion passkeys in use, 90% consumer awareness, and 47% of people more likely to abandon a purchase over a forgotten password. What a passkey actually is, what it costs to add, and when it's worth it for your business.
Read article →